Meta removes scraping language from news sites in terms update
Meta has updated its terms to prohibit scraping content from news sites. This decision follows backlash regarding the use of data to train its AI.
Meta has decided to amend its commercial terms by removing the clause that allowed the scraping of content from websites, including news sites, for the training of its artificial intelligence. This move comes in response to criticism that arose from the interpretation that the company could be using information from various sources without the consent of the content owners.
Why it matters
The removal of this language is significant as it addresses concerns about privacy and ethical data use in the realm of artificial intelligence. At a time when transparency and copyright protection are hot topics, Meta is attempting to distance itself from practices that could be seen as invasive or unfair to content creators.
What we know
The clause that has been removed suggested that Meta could use any content from domains or web pages to develop and improve its products and services, which sparked a strong reaction from the journalism and academic community. Experts like James Grimmelmann have highlighted the importance of this amendment for the integrity of the company's practices in handling third-party information.
What is still unclear
It has not yet been confirmed whether Meta will implement other measures to ensure that its artificial intelligence is not affected by the lack of access to news content. The company has not detailed how it plans to obtain data for training its AI models in the future, leaving the question open about its long-term strategy in this area.
Read at the original source:
The Verge →Related news
 Tech Business
SpaceX plans to become a major wireless carrier
SpaceX has announced its ambitious plan to become a wireless service provider by acquiring low-band spectrum. This move aims to compete with giants like AT&T, T-Mobile, and Verizon.
 Tech Business
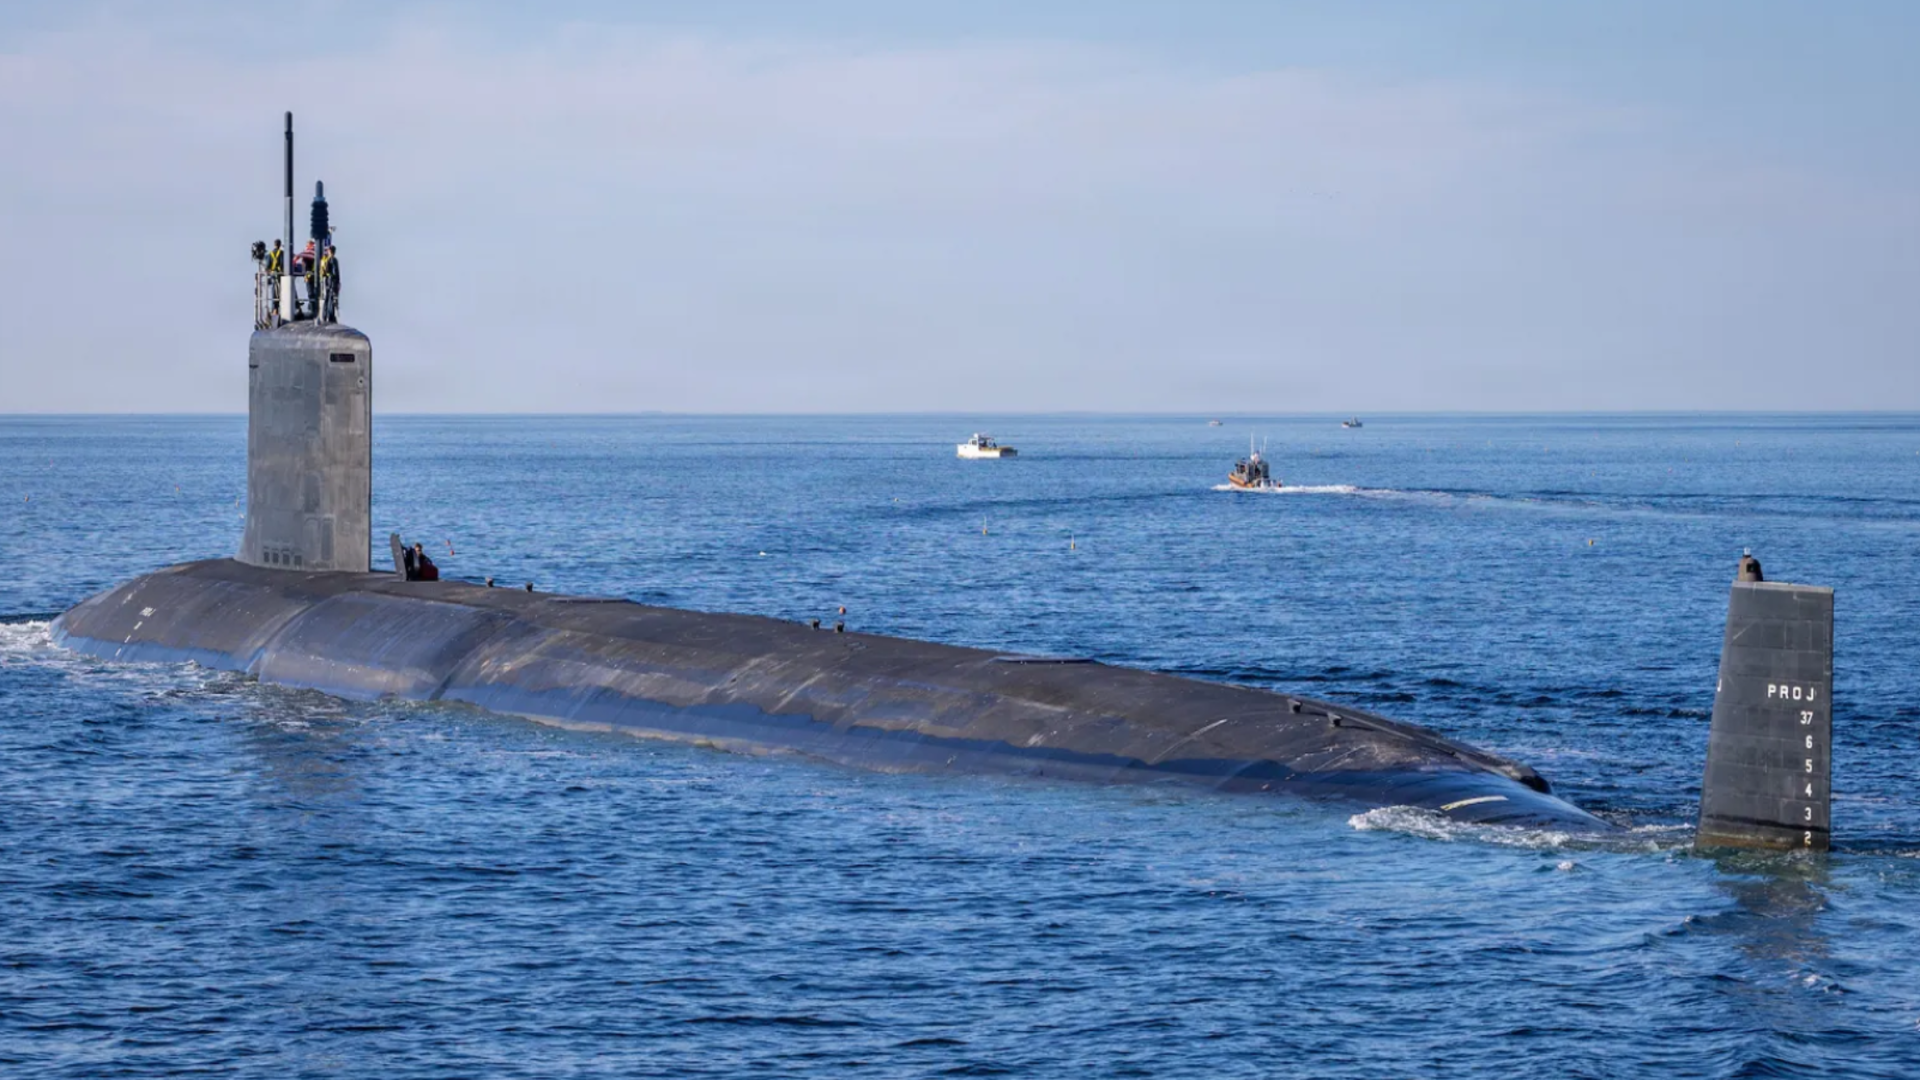
UK Navy employs fire hoses against drones on submarines
British nuclear submarine crews are training to repel drones using water hoses. This method offers an inexpensive and eco-friendly solution against potential aerial threats.
 Tech Business
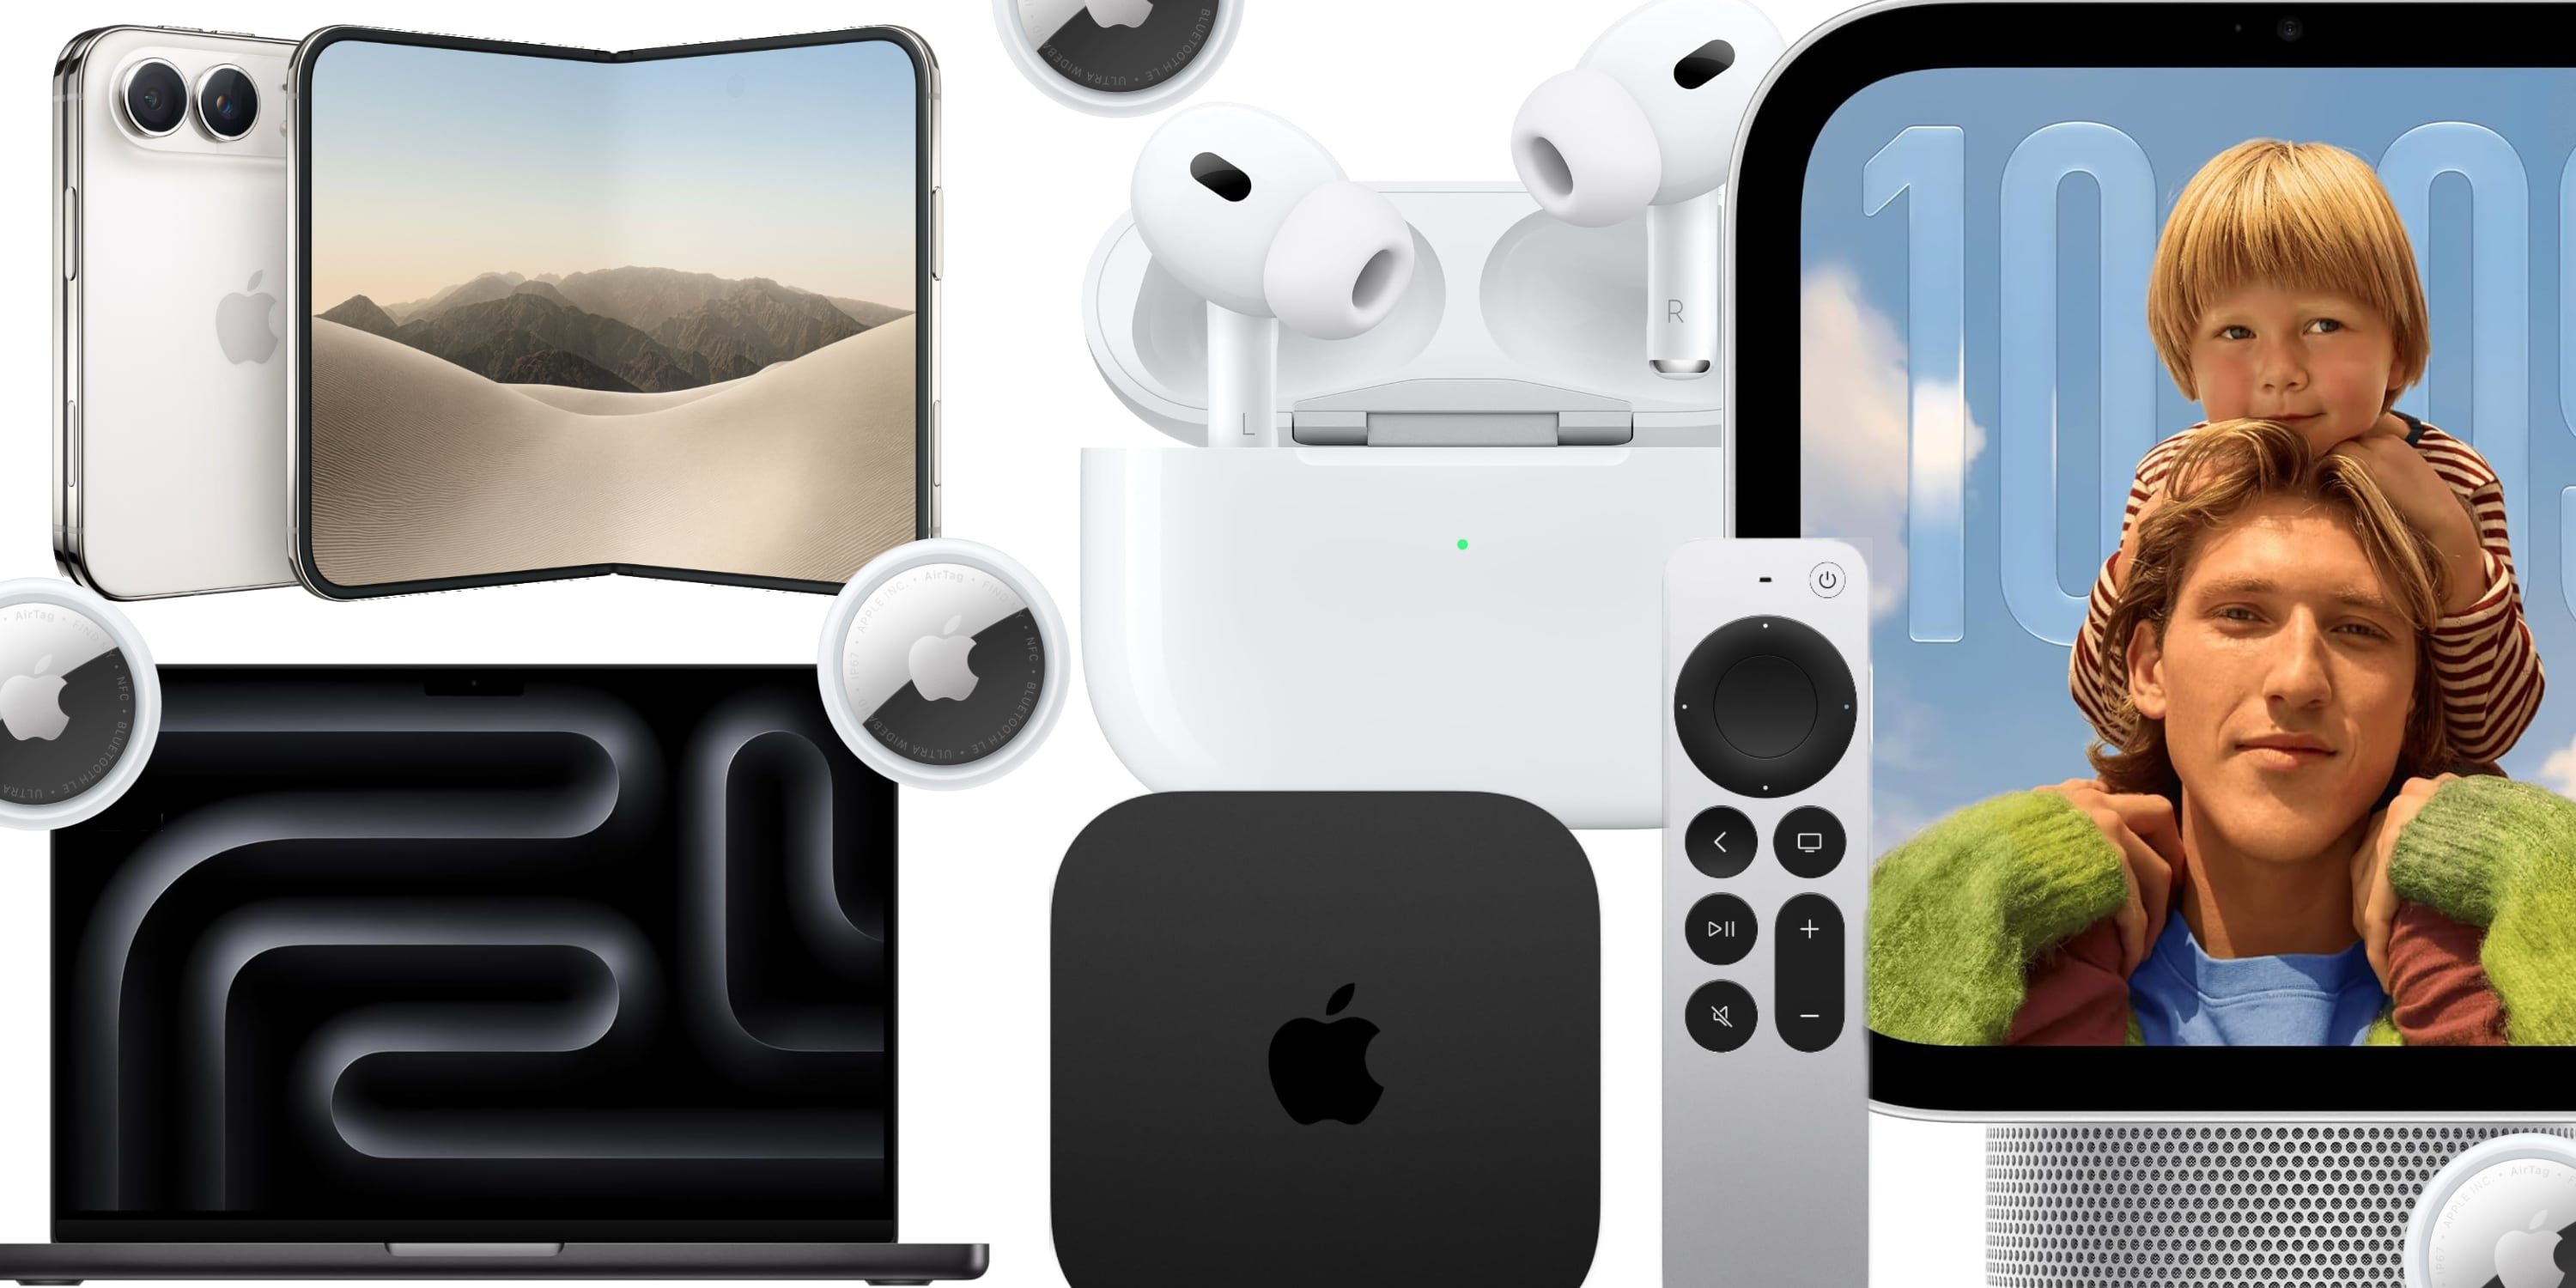
Apple weekend deals: HomeView and more
Apple announces discounts on various products, including AirPods and Apple TV 4K. Take advantage of the offers before they're gone.