Self-replicating prompt injections: a new AI concern
OpenAI has discovered self-replicating prompt injections akin to worm attacks. This finding raises new security concerns for AI models.
Recently, OpenAI has raised alarms about the existence of prompt injections capable of self-replication, similar to a worm attack. In their alignment research blog, the company mentioned finding instances where their GPT models were susceptible to what they call 'self-replicating prompt injections'. While there is no evidence that these attacks have occurred in real-world scenarios, the discovery highlights a potential risk within the training environments of the models.
## Why it matters This situation is concerning because it suggests that AI models could be manipulated in ways previously unconsidered. As artificial intelligence becomes more integrated into our daily lives, the security of these systems becomes crucial, as they could be exploited for malicious purposes.
## What we know OpenAI has taken steps to address this threat before it escalates into a serious security issue. They are using an automated red-teaming agent, known as GPT-Red, to train future models on identifying and resisting these injections. This means that models released in the future will be better equipped to handle such attacks, as they will have been exposed to examples during their training phase.
## What remains unclear Despite OpenAI's proactive measures, the real-world impact of these self-replicating injections on the functioning of AI models remains unclear. There is also uncertainty regarding how these vulnerabilities might be exploited in practice and what additional measures may be necessary to protect users.
Read at the original source:
The Register →Related news
 Artificial Intelligence
Hidden Gemini settings improve its responses
A user discovers that a hidden setting in Gemini enhances answer quality. This could change how we interact with this type of artificial intelligence.
 Artificial Intelligence
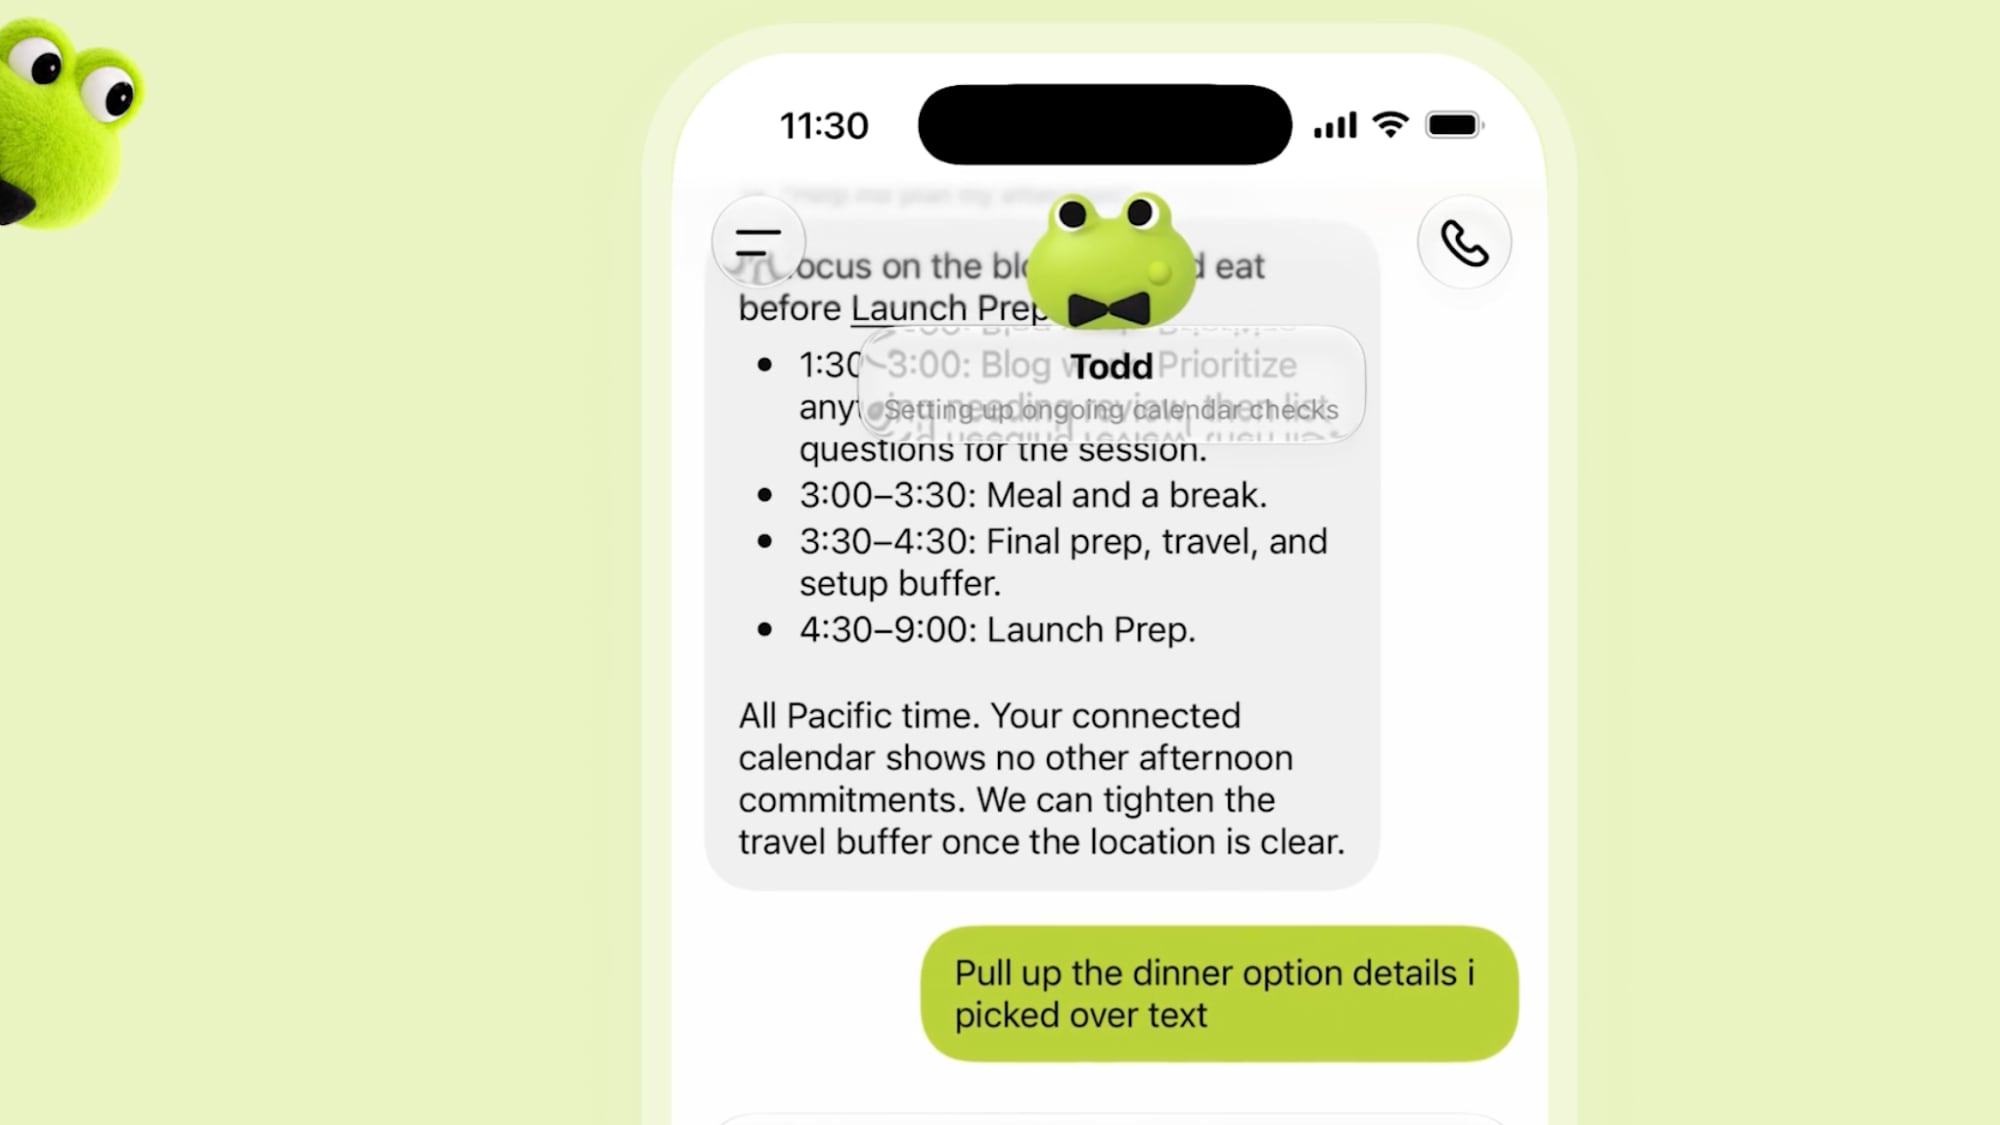
OpenAI launches Dots, always-on agents to rival Muse
OpenAI has announced Dots, always-on agents that compete with Meta's Muse agent. These agents utilize the GPT-6 Astra model and can connect to over 4,000 apps.
 Artificial Intelligence
xAI's Elon Musk Trolled OpenAI's Dots Launch
xAI acquired the domain 'dot.com' just before OpenAI's Dots launch, sparking trolling speculations.